Chunking Documentation for RAG Pipelines
Benchmark data shows chunking strategy matters as much as your embedding model.
Yara Salcedo
Benchmark data shows chunking strategy matters as much as your embedding model.
Structured frontmatter fields improve AI retrieval accuracy where content similarity fails.
Semantic search matches user intent, not just keywords, making docs findable for humans and AI.
Four different AI capabilities hide behind the "AI-powered" label.
Native AI search and assistants now serve both human readers and machine agents equally.
Retrieval systems struggle to find the right knowledge when it matters most.
Vector embeddings solve documentation search by matching meaning, not keywords.
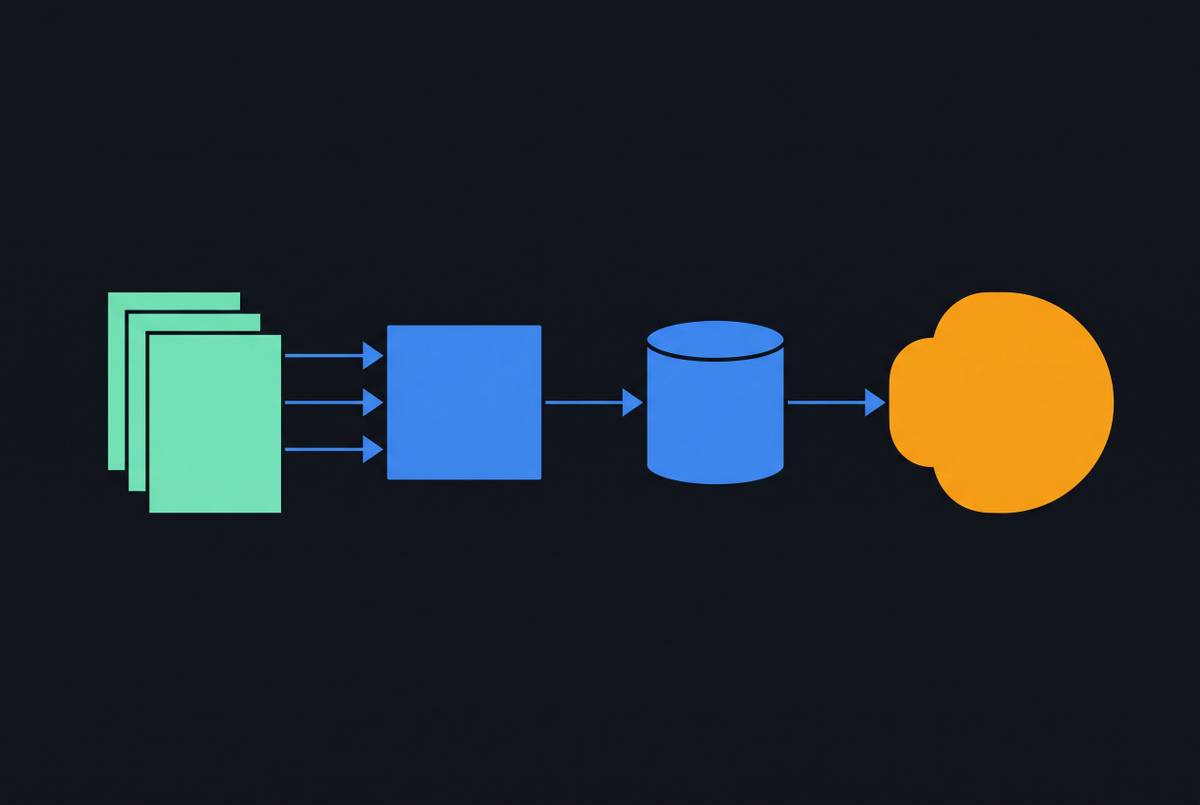
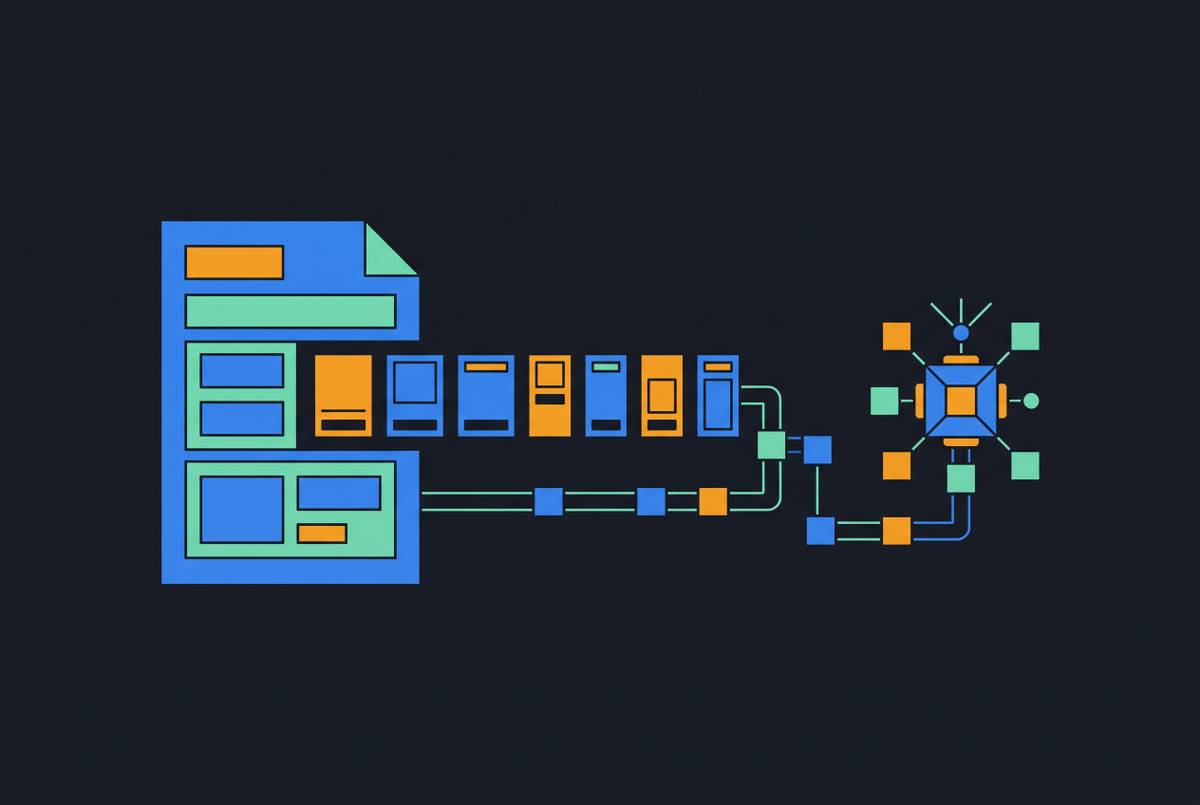
Preserve document structure from the start, or watch your RAG system degrade silently.
Balancing chunk size and loader choice determines whether your documentation RAG actually works.
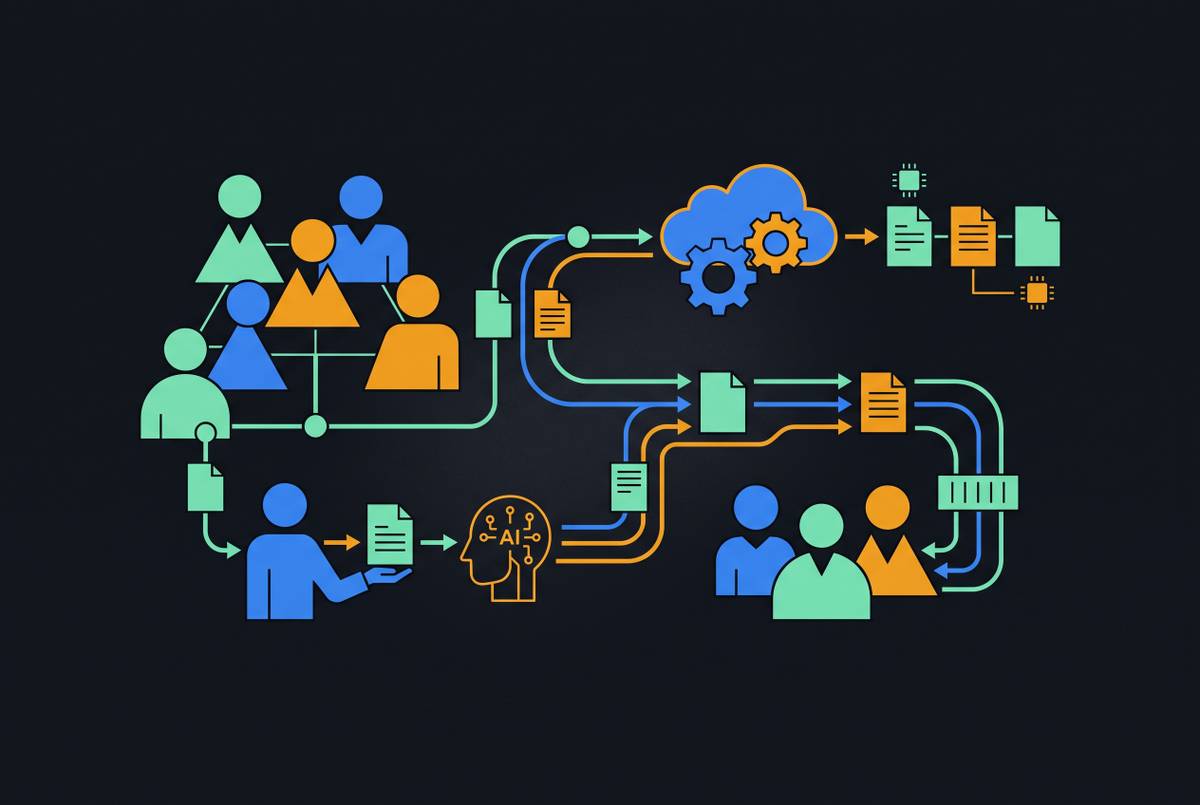
Restructuring doc teams around human-AI collaboration beats simply adding AI tools to old workflows.
Your documentation quality matters far more than your AI vendor choice.
Keeping documentation synced to code deployments cuts debugging time and boosts team velocity.