What Single Source of Truth Actually Means for Agent-Facing Docs
Agents need single resolved facts with timestamps, not outdated documents ranked by relevance.
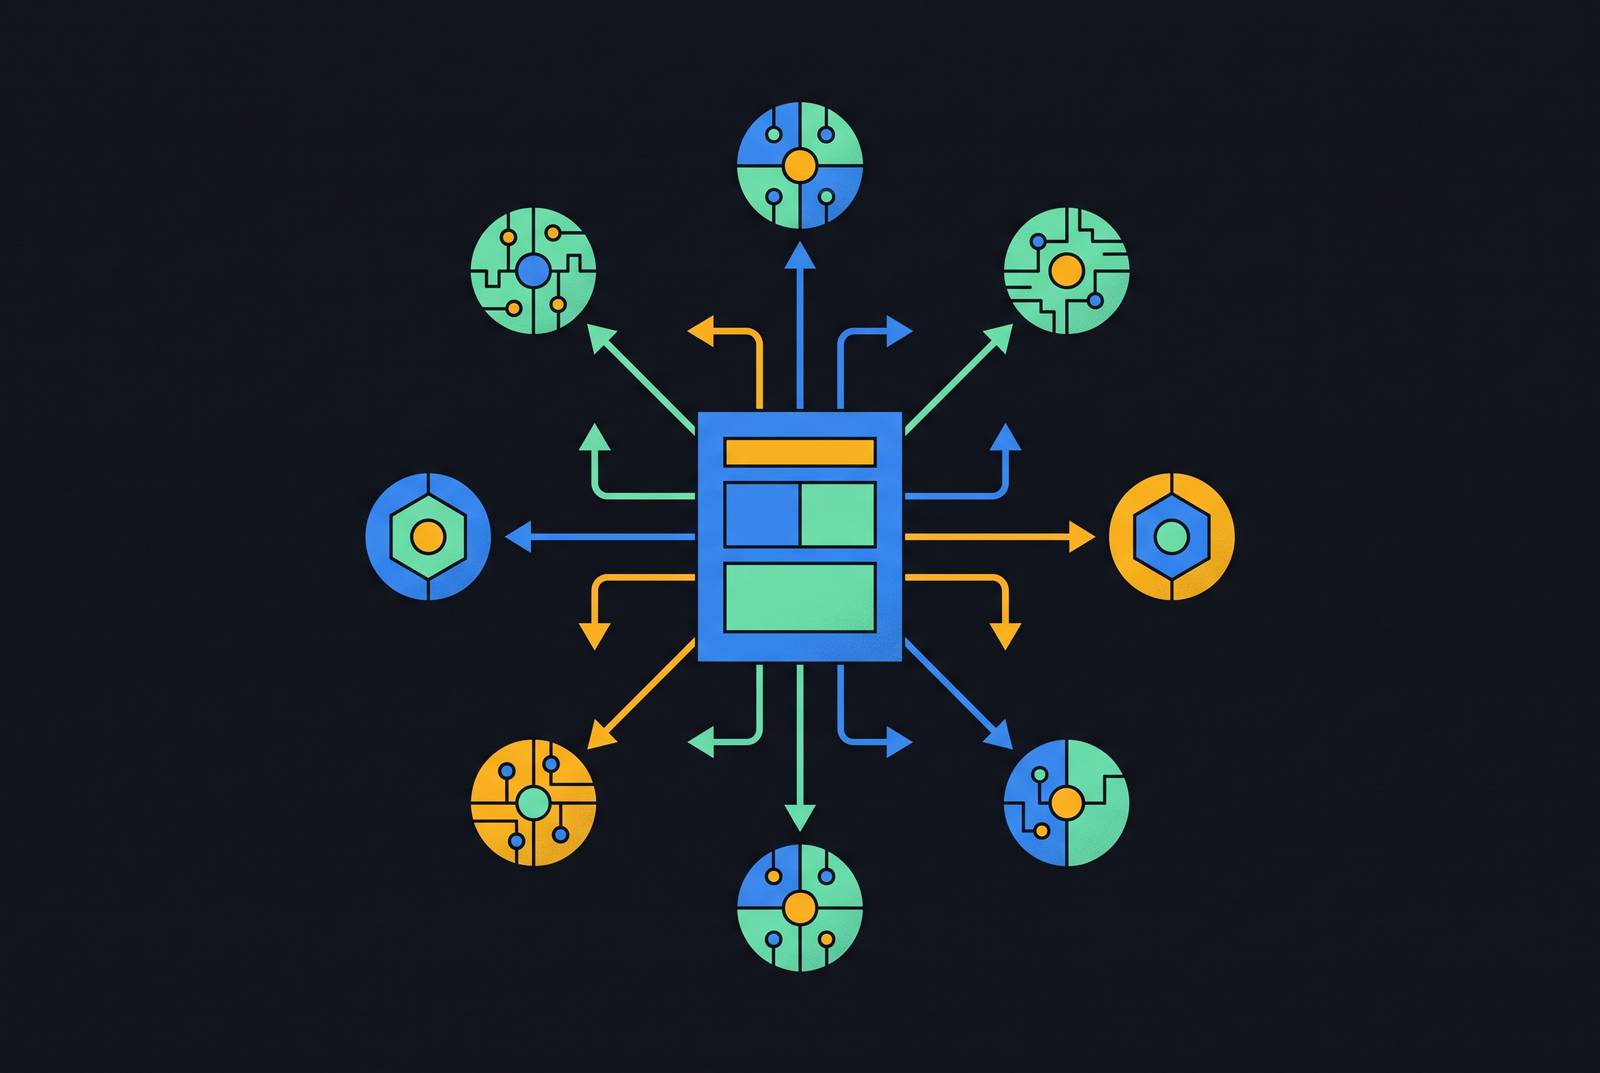
Single source of truth started as a database design principle, and a fairly narrow one: one system owns each record, and every other system references that record. In practice this governed structured data. The CRM owned the customer, the ledger owned the invoice, the HR system owned the employee, and the discipline simply meant that nobody else was allowed to maintain a shadow copy of the same fact. The failure mode under this model was human: someone updated the wrong copy, or updated one system and forgot the other, and a person eventually noticed the mismatch because a person was always the one reading the data. As long as people followed the process, staleness stayed contained. The entire model rested on organizational discipline.
What breaks when an agent is the reader
Organizational discipline works because a human reader brings judgment to what they retrieve. An agent brings none. It states whichever version its retrieval step handed it with exactly the same confidence whether that document is three hours old or three years stale, because nothing in its process asks it to check. That is a retrieval architecture problem, not a failure of the model's reasoning: the model is doing its job correctly given what it was handed, and the break happens upstream of it, in whatever system decided what counted as the answer. Two particular kinds of error do the most damage once agents are the ones reading. Stale-data hallucination happens when the retrieved snapshot is outdated but presented as current. Confabulation happens when no authoritative fact exists at all and the model fills the gap with something plausible-sounding instead. Either one is survivable when a single person asks a single question and gets a single wrong answer back. The damage compounds once multiple agents are chained together: a sales agent quotes a wrong fact, a support agent confirms it because it matches what it retrieved too, a marketing agent publishes it, and the error spreads across every downstream action. At that volume, one unresolved conflict in the underlying data does not produce one wrong answer. It produces a wrong answer repeated across every agent that touches the same question, at a pace no person is positioned to catch before it has already propagated. Reconciliation after the fact, the whole mechanism that made human-mediated SSOT survivable, is structurally impossible to apply at that speed.
Why wikis, search, and vector stores each fail differently
None of the tools organizations already lean on for shared knowledge were built with a non-human, high-speed reader in mind, and each one fails in its own specific way rather than in some generic sense of being "outdated technology." Wikis such as Confluence or Notion fail because the organizational habit of keeping them current rarely survives contact with a fast-moving team: the actual process migrates to Slack, decisions get made in threads, and the official wiki page keeps describing a procedure nobody follows anymore. A wiki page carries a last-edited timestamp, but that timestamp describes the page, not the facts inside it. "The launch is in October" and "the launch moved to December" can sit in two different documents, both technically live, both equally retrievable, with nothing in the page itself telling a reader, human or agent, which one is current. Enterprise search inherits that same problem and adds a second one: it returns every version ranked by relevance, and relevance is not the same question as currency. It will surface an outdated page just as readily as the current one, sometimes more readily, if the outdated page happens to match the query terms more closely. Similarity-based retrieval pipelines run into a version of the same wall under real production conditions: conflicting document versions sitting side by side, business terms that mean different things depending on which team wrote them, and queries that need one exact answer rather than a passage that merely resembles the right answer. Retrieval by text similarity answers a different question than retrieval by authority and time. The embedding closest to a query is not necessarily the fact that is actually still true. And simply dumping more documents into the system does not fix any of this. More outdated material in scope just gives the agent more confident ways to cite the wrong thing. Volume itself becomes a source of degraded accuracy.
The three structural properties an agent-facing SSOT requires
A meaningful SSOT for agents requires three properties working together, and no single incumbent tool, wiki, search, or vector store, holds all three at once. The first is one resolved fact per question. When two sources disagree, the system has to decide which one is current using authority and time rather than text similarity, and it has to record why it made that choice. A fresh message from the process owner should outrank an old wiki page. A signed contract should outrank an email draft. This is resolution: the system hands back a single answer, not a shortlist for the agent to pick from the way enterprise search does. The second property is a time dimension attached to every fact, not just to the document containing it. Without that dimension, temporal conflicts are simply invisible to retrieval, the way they are in a wiki or a vector index today. The third property is a governed semantic layer, a business abstraction sitting between raw enterprise data and the agents consuming it, making sure a term like "revenue," "active customer," or "conversion rate" means precisely the same thing no matter which agent or automated decision is using it. Without that layer, agents resolve ambiguity through inference, and inference at scale fails quietly. Three agents can produce three different answers to the identical business question with no visible alarm until a renewal is lost or a regulatory inquiry opens and someone finally asks why the numbers never matched. Satisfying all three properties at once is an architectural requirement, which raises the question of what that architecture actually looks like when someone tries to build it.
File-level and protocol-level conventions at the infrastructure layer
Two emerging standards and one protocol represent the field's first serious attempt to push SSOT down into infrastructure itself, rather than leaving it as a team habit that erodes the moment people get busy. By mid-2026 it was present across more than 60,000 open-source repositories, a scale that suggests the convention answered a real and widely felt gap. llms.txt addresses a related but distinct need. Introduced by Jeremy Howard of Answer.AI in September 2024, it is a Markdown file placed at the root of a domain, giving AI systems a curated index of the site's most important content along with a one-line description of each. A stale llms.txt is worse than having none. An outdated index does not just fail to help, it actively misleads an agent into pointing at the wrong content with total confidence, which is the identical failure mode the earlier sections describe in wikis and vector stores, just relocated into a newer file format. And llms.txt has a structural limit of its own: it is a community convention with no backing from the W3C, the IETF, or any recognized standards body, and no enforcement mechanism exists behind it. MCP, the Model Context Protocol, works at a different layer. Introduced in 2024 as an open standard, it defines a standardized interface, built on JSON-RPC message exchange, for giving large language models secure and uniform access to external tools and services. It answers the fragmentation of custom connectors and proprietary glue code that different platforms each demanded before it. For agent-facing documentation specifically, the practical payoff is that human readers and AI agents can draw from the same underlying source without a team maintaining two separate pipelines to keep both audiences fed. None of these three, taken alone, fully delivers the three properties the previous section laid out. They are steps toward that architecture, not finished instances of it, and the stale-llms.txt warning is the clearest evidence available that a convention by itself cannot enforce currency. Enforcement still has to come from somewhere, which is exactly the argument some enterprise architects take further than this piece has so far.
The strongest objection: why some enterprise architects argue SSOT is the wrong model entirely
A serious strand of enterprise architecture thinking holds that the classic SSOT model is structurally the wrong model for agents. The objection runs like this: SSOT as originally conceived assumes synchronous, human-mediated access, one person working in one system at a time, backed by the organizational discipline that naturally follows from that pattern. Agentic systems violate all three of those assumptions at once: access is asynchronous, multiple agents touch multiple systems in parallel, and there is no single human moment where discipline gets applied. One might argue that if the foundational assumptions are gone, the term itself ought to go with them. The alternative framing some architects prefer is "governed truth-in-context," which argues the goal was never to consolidate every scrap of enterprise data into one platform, but to deliver the right information to the right workflow at the right moment, with clear controls over how that information gets used once it arrives. But what if these alternatives are not actually competing with the original thesis? Read closely, none of them refute the idea that agent-facing systems need one resolved, authoritative answer per question. They restate it in different vocabulary, built for distributed architectures where consolidation into a single platform genuinely is not realistic. The disagreement is about the name. The destination is the same.
What the documentation layer requires for agent retrieval
Once agents are the ones reading, documentation stops functioning as a communication artifact aimed at human comprehension and starts functioning as retrieval infrastructure: well-written documentation lets an agent produce a correct answer, while poorly written documentation lets it produce a confidently wrong one. That shift carries concrete structural requirements, not just a vague call to "write better docs." Machine-parseable structure matters first: llms.txt output, MCP server support, and genuinely structured Markdown delivery. Without these, a tool like Cursor will either skip the documentation outright or return a wrong answer pulled from whatever outdated source happened to rank highest. FAQs, a format the documentation community had largely dismissed as too simplistic for serious technical writing, turn out to be close to optimal for this purpose precisely because a clear question paired with a clear answer is about as easily parseable as a format gets. A production-grade knowledge base reflects all of this across five distinct layers: document ingestion, hybrid retrieval, reranking, an evaluation framework, and a governed semantic layer for business definitions. Volume does not substitute for any one of those five, the same lesson the earlier section drew from document dumps degrading accuracy. Hybrid retrieval deserves particular attention here: combining BM25 keyword search with vector retrieval through Reciprocal Rank Fusion outperforms either method used alone, because exact-match search and semantic search are solving complementary problems, not competing versions of the same one. Keeping documentation synchronized with product changes is the mechanism that makes the SSOT property architecturally enforceable instead of something a team aspires to and occasionally achieves.
Governance encoded in the system rather than enforced by people
Currency has to be a property built into the system for an SSOT to hold up under agent use, or it quietly rots, and in any context where agents are the reader, only the system-level version survives contact with real usage. Encoding governance into the system rather than relying on people to enforce it means several things have to be true simultaneously. Every fact needs a time dimension: not just when a document was last edited, but when the fact itself became true and when, if ever, it stopped being true. Authority relationships need to be explicit: the system has to know that a process owner's message outranks an old wiki page, and it has to record why one fact superseded another. Business rules need to be written as executable statements with a defined limit and a named owner, not left as prose buried somewhere in a policy document that nobody rereads. "Discounts above a threshold require founder approval" is a rule an agent can actually follow. "We try to protect our margins" is not a rule at all, it is a sentiment, and agents cannot execute sentiments. Retired facts need to be explicitly marked as retired: when a product feature changes name or gets discontinued, the old description has to be flagged as no longer current, or agents will keep citing it out of whatever cached document happens to still exist. And permissions need to travel with the fact itself: if the original source was a private channel or a restricted folder, whatever resolved fact gets derived from it has to inherit that same restriction rather than leaking into contexts where it was never meant to surface. None of this is optional scaffolding layered on top of a working system. Agentic AI needs a persistent, governed SSOT precisely because isolated documents and one-off answers cannot support autonomous, multi-step tasks that cross system boundaries the way agents now routinely do, and no amount of organizational discipline, however well-intentioned, can substitute for governance that the system itself enforces.
Sources
- What Vector Stores Do in RAG Pipelines
- Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering
- Implementing single source of truth in an enterprise architecture
- How to Establish a Single Source of Truth (SSOT) in 2026
- What Is a Single Source of Truth (SSOT) & How to Build One?
- GitHub - hiromaily/docs-ssot: SSOT for Markdown documentation compiler and SSOT checker. · GitHub