How Doc Quality Affects What an Agent Gets Wrong
Stale, ambiguous, or incomplete docs produce predictable failures agents can't overcome.
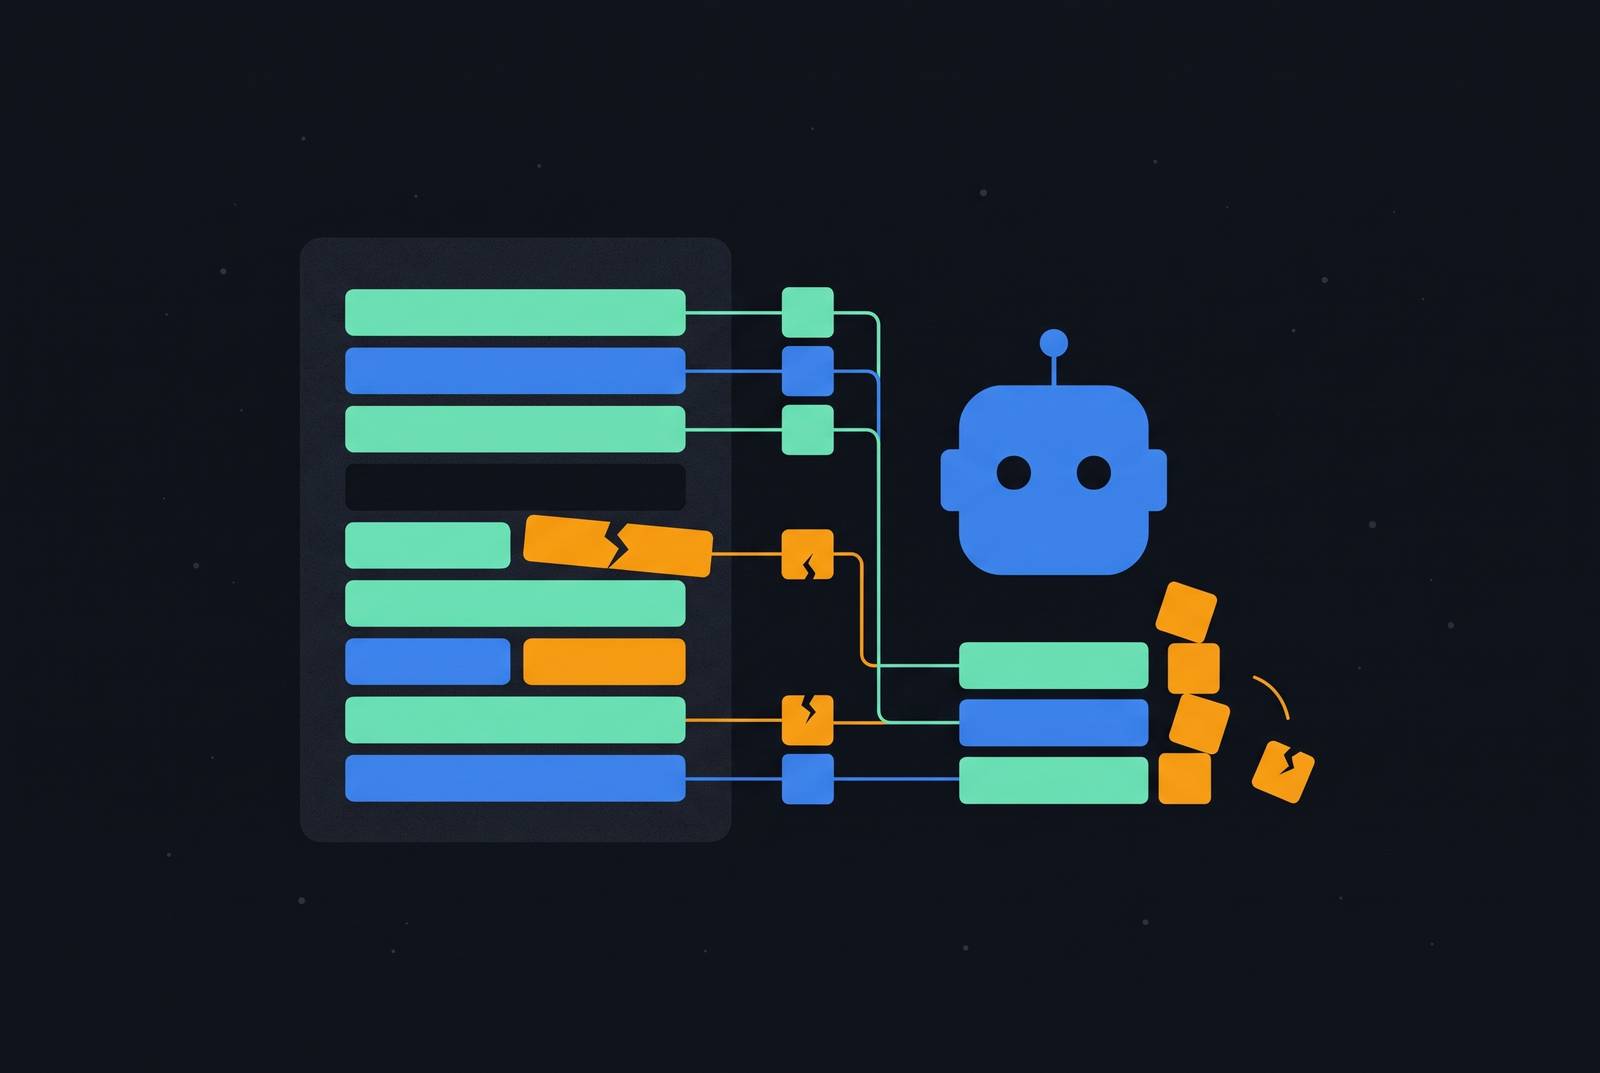
Documentation quality shapes not just whether an agent gets something wrong, but how it gets it wrong. Stale content produces confident, outdated answers. Ambiguous structure leads to wrong choices among available facts. Missing context invites plausible invention. Understanding these differences gives teams a way to trace failures upstream and repair the knowledge behind the answer, rather than repeatedly adjusting the model that produced it.
Why agent errors are often a documentation problem in disguise
An agent confidently tells a user to call an endpoint that has been retired. The steps sound clear, but they fail when the user follows them. A team investigating the answer might tighten the prompt, swap the model, or add a guardrail against unsupported instructions. Yet what if the retrieved documentation explicitly describes that endpoint as the right one? The agent’s answer may follow its evidence closely while still misrepresenting the system.
Teams often debug at the output layer because the output is where the failure becomes visible. A wrong procedure can originate in the material supplied to the agent, even when the agent handles that material correctly. Diagnosis therefore requires checking both whether the agent reasoned correctly and whether its knowledge gave it a sound basis for doing so.
How agents consume documentation and why quality defects translate directly into reasoning errors
Documentation reaches agents through retrieval, context injection, and tool schemas. Retrieval uses semantic or keyword search to select material from a corpus, while context injection places selected chunks in the prompt window. With either pathway, a passage can match the query and still be wrong. A stale passage can closely match a query and displace the current procedure, leaving the agent without the evidence needed to recognize the difference.
Fragmentation introduces another constraint on what the agent can know. Context windows have limits, so a retrieved section may arrive without its surrounding explanation, or a step without its preconditions. The agent must interpret what remains. If the distinction between two procedures exists only in a distant heading, the fragment may not contain enough information to support the right choice.
Tool schemas expose the same problem at the action boundary. They describe what a function does, when to invoke it, and what inputs it needs. Vague descriptions weaken the basis for choosing between tools, while incomplete descriptions leave required conditions unspecified. Some corrupt the facts available to the agent, others obscure applicability, and others leave it to infer facts the documentation never supplied.
Stale documentation and the confident wrong answer
Stale documentation is dangerous because it can remain internally coherent after it stops describing the product. A retired endpoint can still have a clear description, a complete procedure, and an apparently appropriate use case. The passage may have no sign that it is out of date. When retrieval supplies it as relevant evidence, the agent can present the old procedure with the confidence it would give a current one.
A refusal leaves the user without an answer, but makes that limitation visible. An outdated procedure leads the user to act on something that is no longer true. If the endpoint has been renamed or retired, the user encounters a hard failure without being told that the procedure itself is the problem.
A configuration recommendation can be harder to recognize as stale. The documented configuration may have worked in a prior version yet silently break in the current one. In that case, the answer need not contain an obviously invented claim or a visibly broken instruction. Checking whether the answer matches the retrieved passage will not show whether that passage still applies.
Documentation updates need to follow the same cadence as the code changes that invalidate them, so the knowledge exposed to the agent reflects the system it describes. The underlying failure is lifecycle decoupling. When code ships while documentation waits for a separate manual update, the agent inherits the gap between those two workflows.
Ambiguous structure and the agent that chooses wrong when it had the information to choose right
Ambiguous structure presents a different puzzle because the documentation can be accurate and still produce the wrong answer. Two procedures may correctly describe similar scenarios, yet neither clearly states which conditions distinguish them. The agent retrieves relevant material and selects the wrong procedure. It had the information to choose right, but the organization of that information did not make the choice reliable.
This is a navigability gap. Unlike a stale procedure, the selected passage need not be false on its own. It becomes wrong through application to the wrong situation. That distinction changes the repair, because updating the facts will not help if the missing element is an explicit statement of scope.
Conditional instructions make the mechanism especially clear. A step may apply only under one condition, but that qualification can be buried in surrounding prose or separated from the step during retrieval. The agent then applies the instruction unconditionally. What looks like a failure to reason about a condition may instead be a failure to preserve that condition in the material supplied for reasoning.
Human readers can skim, backtrack, and use the surrounding document to reorient. Agents retrieving discrete chunks must derive much of that structure from the chunk itself. The structural treatment is to put scope at the start of each section, use consistent heading taxonomies, and express conditional logic as explicitly labeled, enumerated branches. These changes make the distinction between available procedures explicit in the retrieved evidence.
Missing context and the agent that fills gaps with plausible fictions
Missing context is subtler because nothing in the retrieved passage needs to be wrong or confusing. Documentation may explain what a feature does while omitting why it behaves that way, when not to use it, or how it interacts with another system. The omission leaves a boundary undefined. An agent trying to give a full answer can cross that boundary without knowing where the documentation stops.
What happens when the documentation explains two systems separately but never describes their interaction? Each account may be accurate in isolation. If the systems share state, however, advice that treats them as independent can be locally correct and globally wrong. The missing fact is not another detail about either system alone, but the relationship between them.
Undocumented authentication or rate-limiting behavior creates a similar gap. An agent can present a procedure without warning the caller about conditions that will cause it to fail. The response looks complete because the omitted condition is not visible as an omission. The uninterrupted explanation conceals the point at which grounded instructions give way to inference.
This is why labeling the result a hallucination can stop the diagnosis too early. Agents are trained to produce coherent, complete responses, and incomplete context can prompt them to bridge gaps with plausible inference. That does not make every unsupported answer inevitable or absolve the model of every error. It means that, in this failure mode, invention is a predictable response to insufficient documentation rather than evidence that the model alone is defective.
The documentation’s scope is the underlying constraint. A description of intended use alone may work for someone who already knows the system’s limits, but it leaves the agent without the full knowledge of what works and where it stops working. The corresponding treatment is an audit of what the documentation does not say. Known edge cases, failure modes, interaction effects, and explicit “do not use when” statements define where an otherwise valid answer stops being valid.
How the three failure modes compound when they appear together
Consider a corpus with an old configuration procedure and its current replacement under headings that leave the scope of each unclear. Neither explains how the configuration interacts with an adjacent system that shares state. Retrieval may find the old procedure, or the agent may choose the wrong one from passages that match the query. Even if it selects the current procedure, the undocumented interaction can still lead to unsupported advice.
This combination complicates attribution without making it hopeless. The same query can lead to different kinds of errors from run to run, depending on which flawed chunk retrieval finds. A trace showing accurate, current content may also encourage a team to dismiss documentation as a cause, even when that content omits a necessary condition. Retrieval success is narrower than knowledge sufficiency. Because currency, structure, and completeness can drift independently, their interactions require ongoing maintenance.
Diagnosing which failure mode caused a specific agent error
For a team investigating an error, the practical starting point is the material the agent actually received. Trace-based debugging lets the team see that evidence. Without visibility into retrieved chunks, the team cannot reliably distinguish a bad inference from a bad foundation, which makes observability tooling a prerequisite for this diagnosis. The mapping is a heuristic. Its purpose is to direct attention toward an addressable defect.
When an answer repeats a superseded procedure, the first question is whether the retrieved passage describes an earlier state of the system. When the answer closely matches the source, that may be stronger evidence that the source is stale, without showing that the answer is correct. The relevant comparison is between the passage and the system it purports to describe. Consistency across repeated queries is not required. Retrieval can alternate between semantically similar versions, so an intermittent error can still originate in outdated content.
When the agent retrieves plausible but inapplicable material, the investigation should look for a correct alternative in the corpus. If that alternative is semantically close, or the error changes with query phrasing, section boundaries and heading specificity deserve attention. So does conditional logic buried in prose. The investigation should check whether the retrieved material made the applicable branch explicit.
When the answer goes beyond accurate retrieved material, the team should examine what the source leaves unspecified. Does it say how authentication works, when failure occurs, or how the systems interact in this case? A gap there suggests missing context, while the facts that are there may still be correct. These checks may identify more than one cause in the same trace. The useful endpoint is a specific section that a writer or engineer can repair, rather than an undifferentiated judgment that the agent got something wrong.
What documentation needs to look like when agents are reading it
Prevention requires designing documentation for the way agents receive it. Human browsability remains useful, but it is not the same as retrievability, chunk-level completeness, or temporal accuracy. Each property addresses a different weakness in the evidence available to the agent. A readable page can still yield an unusable fragment. The design unit therefore has to include both the retrieved section and the document viewed from beginning to end.
To prevent staleness, code changes should trigger documentation updates. The documentation and the change that invalidates it should ship together, or the change should be flagged as incomplete. Each section also needs to state its scope clearly, including the version, configuration, or system state it describes. Scope makes currency assessable without reading the whole document. It also helps distinguish current guidance from material that remains valid only under narrower conditions.
To prevent ambiguity, sections should state when they apply and when they do not. Headings need to say what their sections contain clearly enough for retrieval to match them to the questions agents ask, while labeled conditional branches keep each instruction with the conditions it depends on. Completeness requires equal attention to boundaries. Known failure modes, edge cases, and contraindications belong in required sections of the same document, and interactions between systems need explicit descriptions rather than an expectation that the agent will infer them.
Together, these practices make documentation a living knowledge infrastructure integrated into the agent’s workflow. Keeping documentation up to date then helps make agents reliable, instead of being left as an editing task after release. Each piece of documentation must be readable and give an agent enough current, bounded evidence to act correctly.
Sources
- Cascading Hallucination in Agentic RAG: The CHARM Framework for Detection and Mitigation
- When Retrieval Succeeds and Fails: Rethinking Retrieval-Augmented Generation for LLMs
- Characterizing Faults in Agentic AI: A Taxonomy of Types, Symptoms, and Root Causes
- From Agent Behaviour to Agent-Friendly Documentation: An Empirical Study of How Coding Agents Discover, Read, and Write Technical Documentation
- SARC-DQ: Runtime Data-Quality Gating for Agentic AI: Silent Evidence Defects, the Incompetence Shield, and Downstream-Only Remediation
- TRAIL: Trace Reasoning and Agentic Issue Localization
- Where Do Deep-Research Agents Go Wrong? Span-Level Error Localization in Agent Trajectories
- The Misattribution Gap: When Memory Poisoning Looks Like Model Failure in Agentic AI Systems